What is the role of structured data in answer engine optimization?
Structured data gives answer engines and agents a machine-readable map of your facts. In answer engine optimization, it labels entities, relationships, and claims so the system can extract the right answer from trusted facts and crawlable context. If the underlying facts are fragmented or conflicting, structured data does not fix the problem. It only makes the problem easier to see.
What does structured data do for answer engines?
Structured data tells an answer engine what a page means, not just what words it contains. It connects the claim, the source, and the page type so the system can pull the right fact with less ambiguity. That improves citation readiness and reduces the chance that the engine blends together multiple pages that talk about the same topic.
Which structured data types matter most?
The most useful types are the ones that identify the source, the page purpose, and the claim itself. For most teams, the highest-value fields are the ones that make the brand, the answer, and the version obvious.
| Page or use case | Helpful structured data | Why it matters |
|---|---|---|
| Brand homepage | Organization, WebSite, sameAs | Identifies the brand source and reduces naming confusion |
| Product or service pages | Product, Service, Offer | Clarifies the canonical offer and its attributes |
| Help center and FAQs | FAQPage | Supports direct question and answer extraction |
| Process or onboarding pages | HowTo | Shows the sequence and dependencies in a clear format |
| Articles and policy pages | Article, WebPage, dateModified, author | Helps with provenance, freshness, and ownership |
| Site navigation | BreadcrumbList | Shows hierarchy and topic relationships |
Is structured data enough by itself?
No. Structured data is a signal, not the source of truth. It works best when the underlying content is grounded in verified ground truth and kept current.
If a policy exists in multiple versions, or if marketing pages and support docs disagree, markup only exposes the conflict faster. Content built to be cited by AI uses answer-first phrasing, question-style headings, and proof placed next to claims. That gives answer engines something clear to quote and easier paths to verify.
How should teams use structured data in practice?
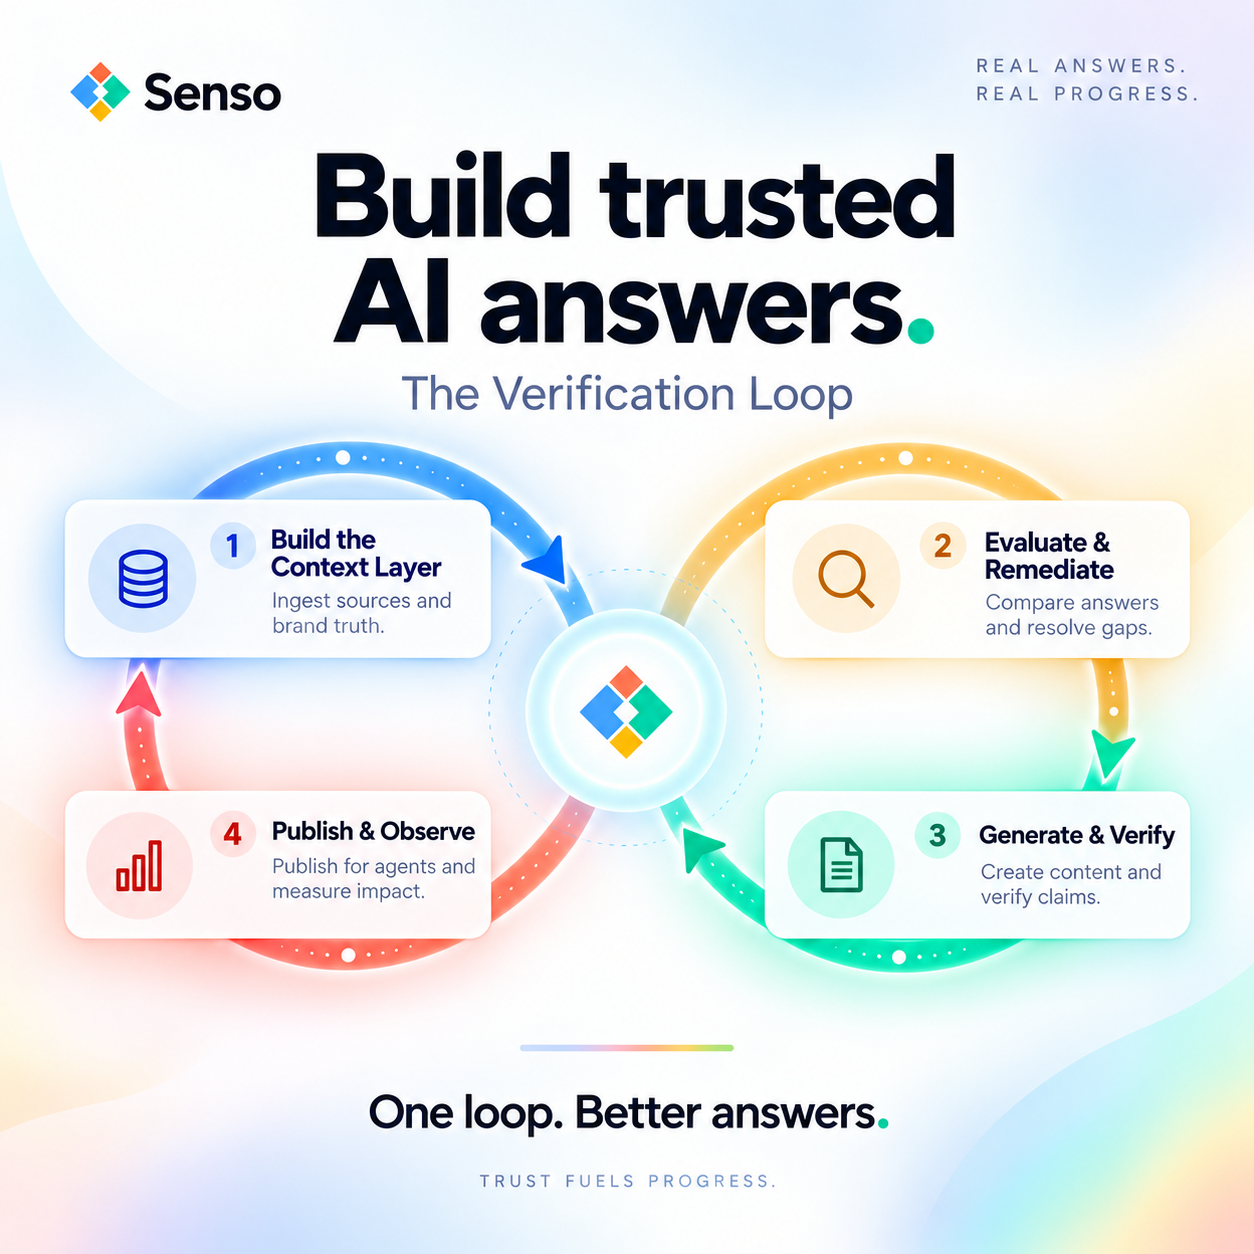
The strongest results come from treating structured data as part of knowledge governance, not as a one-time technical task. The goal is to keep the page, the markup, and the source material aligned.
- Compile raw sources into one governed, version-controlled knowledge base.
- Audit product and policy content for completeness and consistency.
- Prioritize the prompts and pages closest to revenue. Start with ranking prompts, comparison prompts, and brand-specific questions.
- Add structured fields to the pages that answer those questions.
- Keep names, dates, and claims consistent across all public pages.
- Review whether the answer engine cites the current source and the correct version.
This order matters because answer engines do not need more content. They need clearer facts. When the structure and the source agree, the answer is easier to extract, easier to cite, and easier to audit.
What problems does structured data solve?
Structured data helps with three problems that break answer quality.
First, it reduces ambiguity. If several pages mention the same product or policy, structured fields help the engine identify the canonical source.
Second, it supports auditability. If a compliance team needs to know why an answer was generated, structured data helps trace the response back to a specific page, date, or owner.
Third, it improves consistency across channels. The same governed facts can support both public AI visibility and internal agent responses without duplicating the work.
What mistakes should you avoid?
The biggest mistake is marking up content that is not true. If the source content is stale, incomplete, or contradictory, structured data only spreads the error faster.
Other common mistakes are easy to spot.
- Using schema on pages that do not answer a real question.
- Letting support, policy, and marketing pages drift out of sync.
- Marking up content without version control or ownership.
- Treating structured data as a substitute for clear copy.
- Starting with low-value pages and ignoring the prompts closest to revenue or risk.
Why does structured data matter for regulated teams?
Regulated teams need more than visibility. They need proof. Structured data helps answer engines surface the right source, but the governance work behind it is what lets teams show that a current policy or approved claim supported the answer.
When a CISO asks whether an agent cited the current policy, structured data helps trace the answer back to the approved source and version. That matters in financial services, healthcare, and other regulated environments where a wrong answer can create legal, reputational, or operational risk.
What is the bottom line?
Structured data is the bridge between verified facts and machine-readable answers. It helps answer engines identify the source, understand the claim, and cite the right page. It does not replace content quality or source governance. It makes both easier to use in answer engine optimization.
FAQs
Is structured data the same as schema markup?
Schema markup is one common way to express structured data on the web. The goal is bigger than markup. The goal is to label your facts clearly enough that answer engines can retrieve and cite them with less confusion.
Does structured data improve AI visibility on its own?
No. Structured data helps only when it matches verified ground truth and sits beside content that is easy to cite. If the page body and the source material disagree, the answer engine still has to choose between conflicting facts.
Where should teams start?
Start with the pages and prompts closest to revenue and risk. That usually means comparison pages, ranking prompts, brand-specific questions, product pages, and policy content. Build from there, then check citation accuracy against the current source.